AI TEVV gives QA teams a disciplined way to test, evaluate, verify, and validate AI systems before they affect customers, staff, or regulated decisions. For AI products, quality is not limited to whether a feature works once; it includes whether model behavior remains useful, fair, secure, explainable enough for its context, and governable over time.
TEVV is a lifecycle approach for determining whether an AI system is fit for its intended use. QA teams should translate product risks into measurable evaluation tasks, acceptance criteria, monitoring signals, human review rules, and audit-ready evidence. The practical goal is not to prove that a model is perfect, but to show that known risks are controlled and that failures can be detected, escalated, and corrected.
What TEVV Means for QA Teams
TEVV stands for test, evaluation, verification, and validation. In conventional software QA, these ideas often appear as unit tests, integration tests, requirements checks, and user acceptance testing. In AI systems, the boundaries blur because a model can return probabilistic, context-dependent, or non-deterministic outputs, especially when it uses generative AI, retrieval, ranking, classification, or autonomous decision logic.
The NIST TEVV-Athlon framework is useful because it frames AI evaluation as a structured discipline rather than a one-time benchmark. For QA leaders, that means shifting from pass-fail scripts alone to a portfolio of evidence: curated test sets, adversarial cases, scenario reviews, monitoring data, model cards, incident logs, and sign-off records.
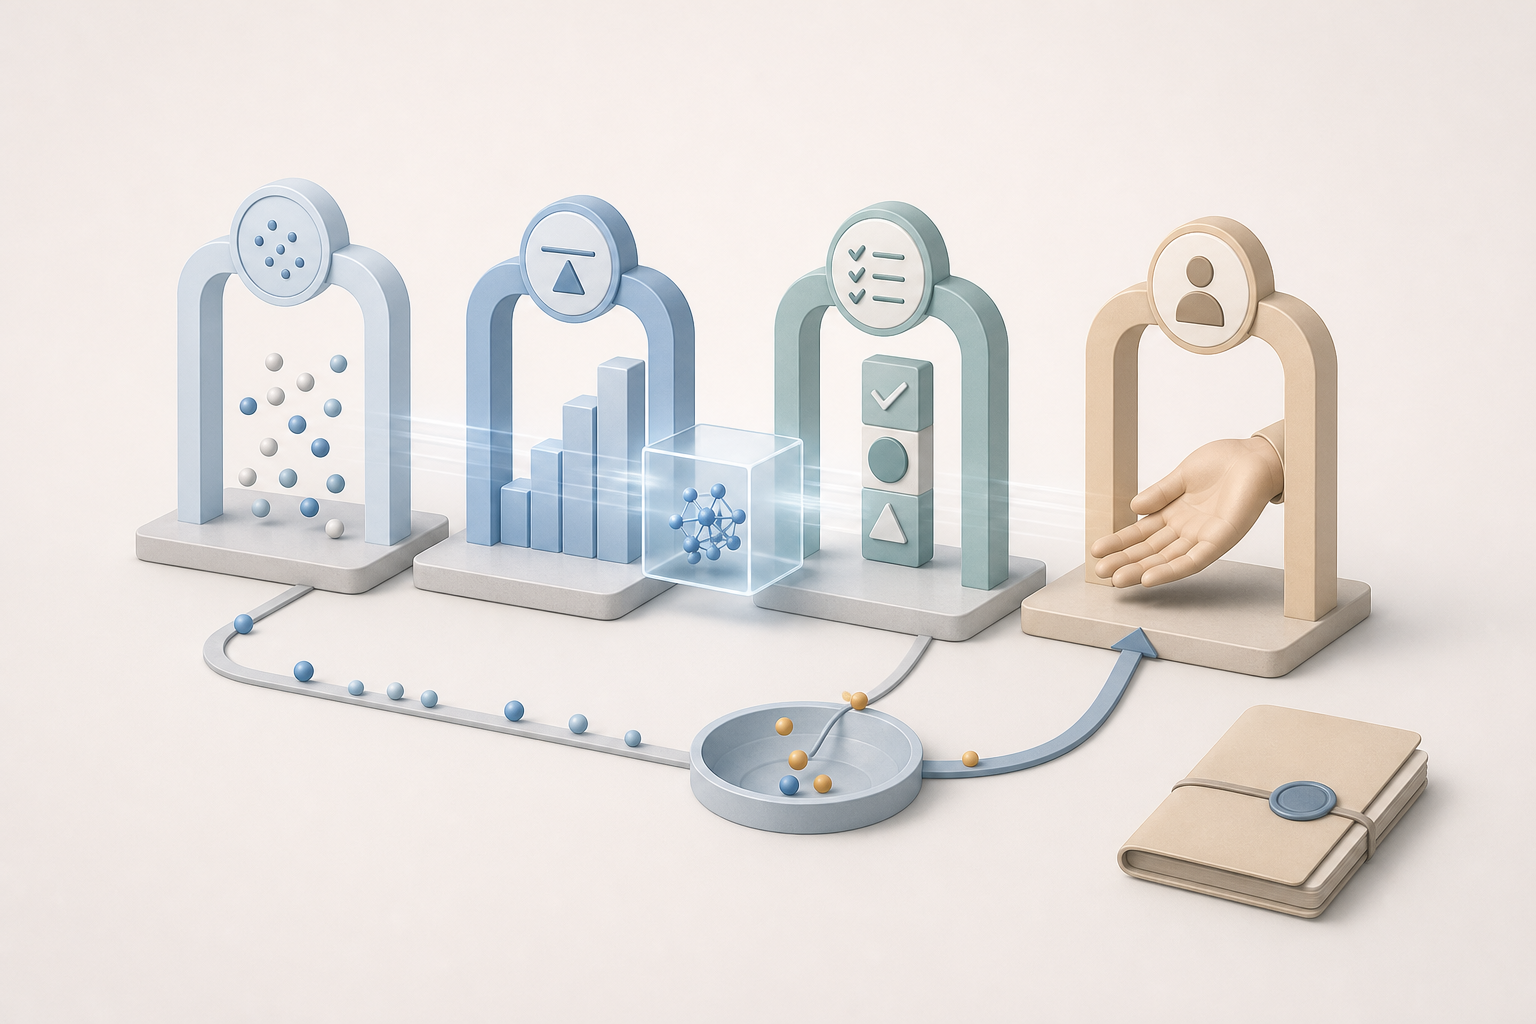
In practical terms, each part of TEVV asks a different quality question. Testing asks, "What happens when we exercise the system?" Evaluation asks, "How good is the result against defined criteria?" Verification asks, "Did we build the system as specified?" Validation asks, "Does this system meet the real user and business need in its operating context?"
Map AI Risks to Test Types Before Choosing Metrics
The most common mistake in AI system evaluation is starting with a fashionable metric before defining the risk. Accuracy, precision, recall, toxicity rate, groundedness, latency, refusal quality, fairness disparity, and human override rate are not interchangeable. A medical triage assistant, a support chatbot, and an invoice classifier need different evidence even if all three use machine learning.
| AI risk | TEVV focus | QA evidence to collect |
|---|---|---|
| Incorrect or unsafe output | Validation and scenario evaluation | High-risk user journeys, expert review notes, severity ratings, rollback criteria |
| Bias or disparate treatment | Evaluation across segments | Segmented metrics, representative evaluation sets, review of proxy variables |
| Hallucination or unsupported claims | Groundedness testing | Reference-based checks, source attribution review, refusal and uncertainty cases |
| Security abuse or prompt injection | Adversarial testing | Red-team prompts, tool-use constraints, blocked action logs, exploit reproduction steps |
| Model drift after release | Monitoring and revalidation | Input distribution trends, output quality samples, alert thresholds, retraining triggers |
| Poor operational fit | Human-in-the-loop validation | Escalation rules, reviewer workload data, support tickets, user feedback themes |
This risk-first approach aligns with broader risk prioritization practices. Teams that already use product signals to shape test scope can extend the same thinking to AI behavior, especially when deciding what must be evaluated before launch and what can be monitored after release. See our guide to using product signals to choose test scope for a related way to connect testing effort to user and business risk.
Build Evaluation Sets That Represent Real Use and Real Failure
An evaluation set is a controlled collection of inputs, expected behaviors, references, rubrics, and metadata used to judge model performance. It is not just a spreadsheet of examples. For AI TEVV, the evaluation set becomes a reusable quality asset that supports release decisions, regression checks, incident investigations, and audits.
What should go into an AI evaluation set?
A strong evaluation set includes normal cases, edge cases, abuse cases, and known difficult cases. It should also include metadata that matters for risk: language, region, customer type, data sensitivity, user intent, source system, domain topic, or protected-class proxy where legally and ethically appropriate. Without metadata, teams cannot tell whether a high average score hides unacceptable failures in one important segment.
For generative systems, expected behavior may be a rubric rather than a single exact answer. For example, a support assistant response might be judged on factual correctness, policy compliance, tone, completeness, citation quality, and whether it escalates when the user describes a high-risk issue. For classifiers, expected behavior may be a label plus confidence bands and escalation rules.
Protect the evaluation set from contamination. If the same examples are repeatedly used for prompt tuning, fine-tuning, or model selection, they become less useful as a holdout signal. QA teams should maintain a visible split between training data, development evaluation data, release-gate evaluation data, and sequestered challenge data. NIST’s Artificial Intelligence Technology Evaluation initiative describes objective assessment with common metrics and sequestered evaluation environments as part of its evaluation direction, according to the NIST AITE announcement.
Turn Acceptance Criteria Into Release Gates
Acceptance criteria for AI systems should combine quantitative thresholds with qualitative review. A single score rarely captures production readiness. QA should define minimum model performance, prohibited failure classes, monitoring readiness, human escalation behavior, data-handling checks, and documentation requirements.
Here is a simplified, escaped configuration-style example of how a team might express release gates for a customer-support assistant. The values are illustrative; real thresholds should come from product risk, domain standards, user research, legal review, and operational tolerance.
ai_release_gate:
  system: customer_support_assistant
  model_version: candidate-2026-10
  evaluation_sets:
    regression: locked_support_cases_v5
    safety: adversarial_support_prompts_v3
    groundedness: policy_reference_cases_v2
  required_results:
    task_success_rate: "at_or_above product_threshold"
    critical_policy_violations: 0
    unsafe_escalation_failures: 0
    unsupported_claims: "below approved_threshold"
    latency: "within service_objective"
  human_review:
    required_for:
      - refund_dispute
      - legal_threat
      - account_takeover
      - self_harm_language
    reviewer_can_override_model: true
  monitoring:
    drift_alerts_enabled: true
    sampled_output_review_enabled: true
    incident_owner_assigned: true
  release_decision:
    approvers:
      - qa_lead
      - product_owner
      - risk_representative
The key is not the syntax. The key is that each gate creates evidence. If a team cannot show which evaluation set was used, which model version was tested, who approved exceptions, and what will be monitored after launch, the release is difficult to defend.
Verify the System Around the Model
AI quality is not only model quality. Many production failures come from the system that surrounds the model: data pipelines, retrieval indexes, feature stores, prompt templates, caching layers, guardrails, authorization boundaries, tool integrations, and user interfaces. Verification should confirm that these components implement the approved design.
For retrieval-augmented generation, verify that the system retrieves from approved sources, respects access controls, handles stale documents, and does not expose restricted content. For an AI agent, verify that tool calls require the right permissions, dangerous actions are blocked or require confirmation, and logs capture the context needed for investigation. For batch scoring, verify input schema validation, idempotency, retry behavior, and downstream handling of low-confidence outputs.
AI systems are often distributed systems with additional uncertainty. If your product depends on queues, asynchronous workers, external model endpoints, or delayed feedback loops, combine TEVV with resilient automation practices similar to those used in testing distributed systems.
How is verification different from validation for AI?
Verification checks whether the system was built according to requirements and controls. Validation checks whether the resulting system is appropriate for its intended use. A chatbot can be verified to call the right retrieval index and still fail validation if users cannot trust its answers or if it escalates urgent cases too slowly.
This distinction matters for sign-off. Engineering may demonstrate that the pipeline, prompts, access controls, and deployment configuration match the specification. Product, risk, and QA still need to decide whether the observed behavior is acceptable for the real users, real environment, and foreseeable misuse cases.
Monitor Drift, Bias, and Performance After Release
AI TEVV does not end at launch. Models can degrade when user behavior changes, source data shifts, policies update, adversaries adapt, or an upstream provider changes model behavior. Monitoring is the production extension of evaluation, not a substitute for pre-release testing.
Useful monitoring signals include input distribution changes, confidence trends, refusal patterns, escalation volume, reviewer disagreement, user feedback, latency, cost, harmful-output reports, and segment-level performance where appropriate. For generative systems, sampled human review remains important because not every quality issue is captured by automated scoring.
Teams should define drift response playbooks before alerts fire. A drift alert might trigger sampling, a targeted re-evaluation, temporary routing to human review, rollback to a previous model version, prompt adjustment, retrieval index refresh, or retraining. The worst pattern is an alert that no one owns.
When should a model be revalidated?
Revalidation should occur whenever the intended use, user population, model version, prompt strategy, retrieval source, data pipeline, policy environment, or risk profile changes materially. It should also occur after serious incidents or repeated near misses. Minor infrastructure changes may need regression checks, while material behavior changes require a broader validation review.
Design Human-in-the-Loop Review as a Control, Not a Decoration
Human review is often added late as a vague safety measure. That is not enough. A human-in-the-loop control should specify which cases are routed, what reviewers see, what decisions they can make, how overrides are recorded, and how disagreements feed back into evaluation.
Good review design also protects reviewers from overload. If every uncertain case escalates, humans become the bottleneck and may rubber-stamp outputs. If too few cases escalate, the system may silently automate decisions that require judgment. QA can help by testing routing rules, measuring reviewer agreement, sampling non-escalated cases, and checking whether escalation instructions are understandable.
Escalation is especially important for high-impact decisions, sensitive content, legal or financial commitments, vulnerable users, and situations where the model lacks sufficient context. The acceptance criterion should not merely say "human review exists." It should define review effectiveness.
Make Reporting and Governance Audit-Ready
Governance evidence should be produced as a byproduct of disciplined TEVV work, not assembled in a panic after an incident. At minimum, teams should retain the tested model version, system configuration, evaluation sets, metrics, rubric definitions, known limitations, approval records, risk exceptions, monitoring plan, and incident response owner.
Release reports should be understandable to both technical and non-technical stakeholders. A QA lead may include detailed metric tables and failure analysis, while an executive summary should state the intended use, key risks, readiness decision, unresolved limitations, and monitoring commitments. Risk and compliance stakeholders need traceability from identified risks to controls and evidence.
Use exception handling carefully. An exception is not a hidden pass. It should name the risk, explain why release is still acceptable, identify compensating controls, assign an owner, and set an expiry or review date. Permanent exceptions become unmanaged risk.
Common Pitfalls That Weaken AI TEVV
- Optimizing for a leaderboard instead of the product. Public benchmarks can be informative, but they rarely represent your users, policies, data, or failure costs.
- Using averages without segment analysis. A good overall score can mask unacceptable performance for a language, region, product tier, or user group.
- Testing only friendly prompts. Real users are ambiguous, impatient, creative, and sometimes malicious. Evaluation sets need adversarial and messy cases.
- Ignoring the non-model system. Retrieval, access control, logging, workflow routing, and downstream actions can create serious failures even when model output looks plausible.
- Treating monitoring as an operations-only task. QA should help define what must be sampled, alerted, reviewed, and revalidated.
- Approving releases without evidence lineage. If the team cannot reproduce what was tested and approved, governance becomes fragile.
Key Takeaways
- AI TEVV is a lifecycle quality approach that combines testing, evaluation, verification, validation, monitoring, and governance evidence.
- Start with product and user risks, then choose metrics and evaluation methods that directly address those risks.
- Evaluation sets should include realistic, edge, adversarial, and segment-tagged cases, with protected holdout data for release decisions.
- Acceptance criteria should cover model behavior, system controls, human review, monitoring readiness, and auditability.
- Verification proves the AI system was built as specified; validation proves it is fit for its intended use.
- Post-release monitoring should have named owners, response playbooks, and triggers for revalidation.
- Human-in-the-loop review is effective only when routing, authority, evidence, and feedback loops are explicitly tested.