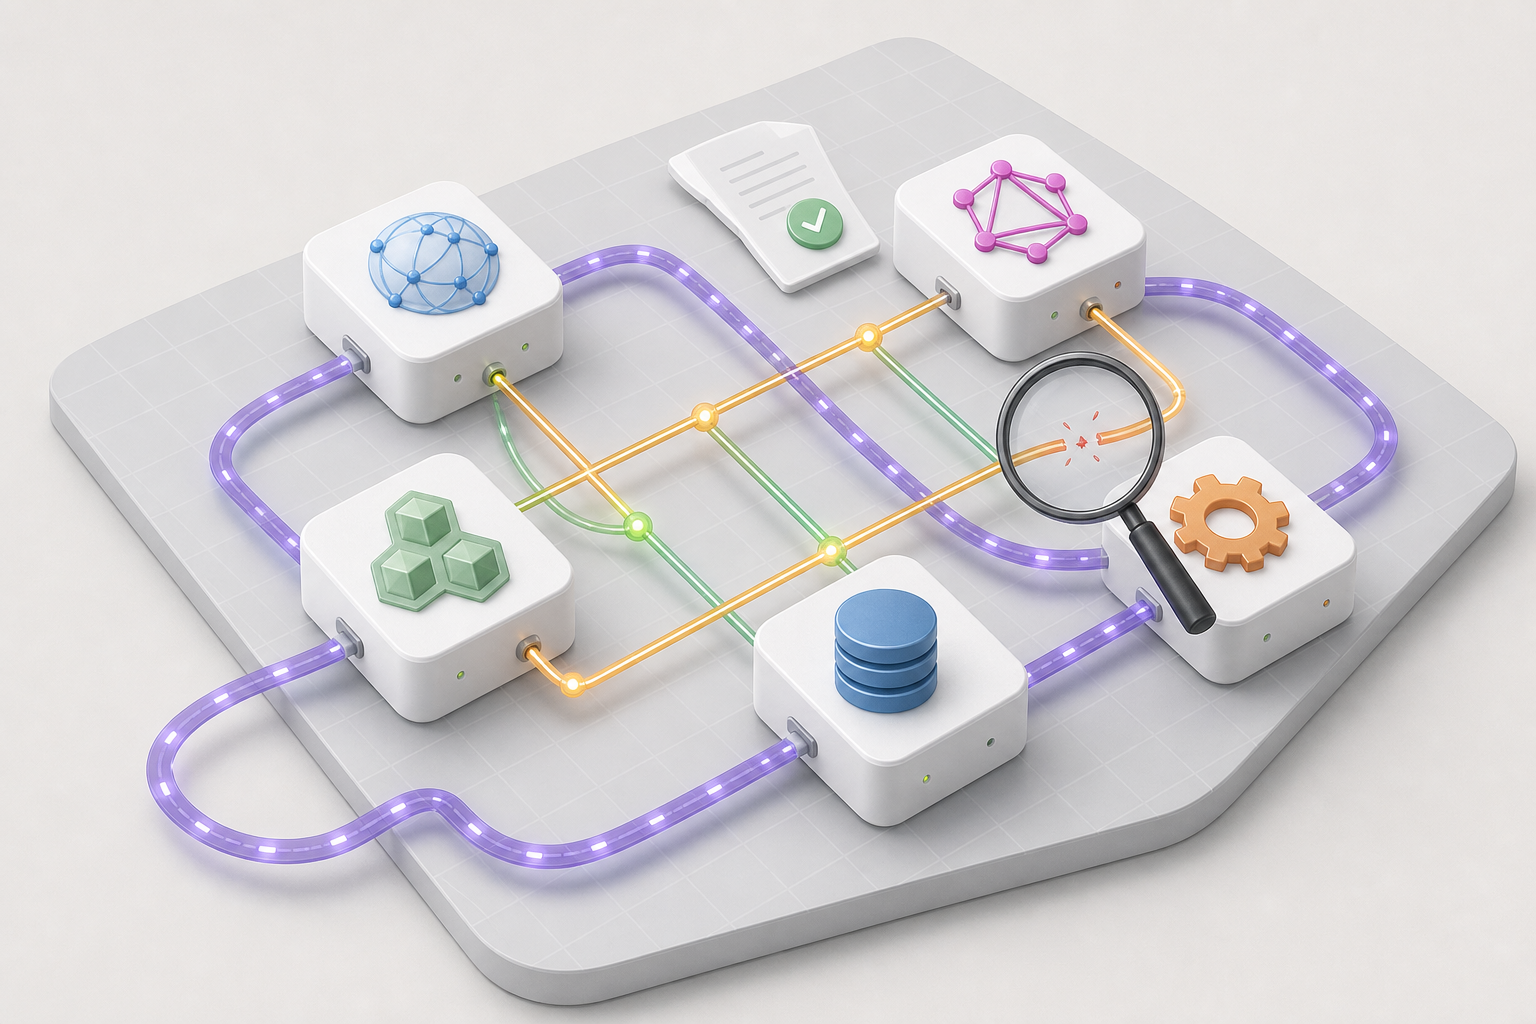
A microservices testing strategy is a risk-based plan for proving that independently deployed services work correctly alone, at their API boundaries, and inside a distributed runtime. The hard part is not adding more tests; it is choosing where API testing microservices, contract testing microservices, and distributed system testing give the fastest signal without recreating production in every pipeline.
A strong microservices testing strategy combines focused service-level API tests, consumer-driven contract tests, selective integration checks, and observability-backed debugging. Use API tests to validate behavior, contract tests to protect compatibility, and distributed tracing to explain failures across service boundaries. Keep full end-to-end tests small because they are expensive, slower, and more fragile than boundary-level validation.
Design a Microservices Testing Strategy Around Risk and Ownership
A microservices testing strategy should map each test type to a specific failure risk and a clear owning team. Without ownership, the suite becomes a shared dumping ground where failures are ignored because every team assumes another service caused the breakage.
Microservices are independently deployable services that own a bounded business capability and communicate through APIs or asynchronous messages. That independence changes the test economics: a defect may appear only when version drift, network latency, data propagation, or a downstream schema change interacts with otherwise valid code.
Distributed system testing is the practice of validating behavior across multiple services, networks, data stores, queues, and failure modes. It should not mean running every browser journey through every real dependency on every commit; that pattern usually creates slow feedback and non-deterministic failures.
For most mature teams, the effective pyramid is weighted toward service tests and contract tests, with a smaller number of workflow-level integration and end-to-end tests. Teams that rebalance this way commonly report 30% to 50% faster pull request feedback because fewer failures depend on shared environments.
How should test ownership shift in microservices?
Test ownership should follow the service contract, not the test execution environment. The team that owns a service should own its provider verification, API behavior tests, schema compatibility, telemetry quality, and incident-grade diagnostics.
Platform QA or central test engineering can provide frameworks, reusable libraries, environments, and quality gates. They should not become the manual router for every broken cross-service test because that removes accountability from service teams.
A practical ownership model labels tests by service, consumer, contract, dependency type, and failure severity. This metadata allows CI systems to notify the right team and helps release managers decide whether a failed check blocks deployment or triggers investigation.
When should integration tests run against real dependencies?
Integration tests should use real dependencies when the risk comes from protocol behavior, persistence semantics, authorization policy, message ordering, or infrastructure configuration. They should use virtualized or mocked dependencies when the purpose is simply to confirm the local service handles expected responses.
The mistake is treating real dependencies as automatically more realistic. A shared integration environment with stale data, partial deployments, and unstable queues often produces less useful feedback than a hermetic service test with accurate contracts.
Use real dependencies for narrow, high-value checks such as payment authorization flows, identity token validation, event publication, and cross-database consistency. Use stubs for broad permutations of edge cases, timeout handling, malformed responses, and consumer-specific business rules.
API Testing Microservices at the Service Boundary
API testing microservices is the validation of service behavior through REST, GraphQL, gRPC, or messaging interfaces without relying on the internal implementation. It is the most important executable specification for a service because consumers experience the API, not the code structure.
A good API suite checks business behavior, compatibility, authorization, idempotency, pagination, error models, rate limits, and observability headers. Status-code-only checks create false confidence because a service can return 200 while silently dropping fields, leaking data, or violating a workflow invariant.
REST is an architectural style for resource-oriented APIs that commonly use HTTP methods, status codes, headers, and JSON payloads. GraphQL is a query language and runtime for APIs where clients request exactly the fields they need from a typed schema.
What should REST API tests verify beyond status codes?
REST API tests should verify resource state transitions, response schemas, error envelopes, authorization boundaries, caching semantics, and idempotent retry behavior. The most damaging production API defects are often not hard failures; they are subtly wrong responses that consumers successfully parse.
For example, a checkout service test should assert that a duplicate idempotency key does not create a second order, that a forbidden user cannot read another account, and that a downstream inventory timeout returns a retryable error contract. These checks belong at service boundary level because they are faster and more diagnosable than equivalent browser tests.
Schema validation should be strict on provider obligations and tolerant where consumers allow extension. Additive fields should not break clients, but removed fields, changed types, and altered requiredness must be treated as compatibility risks.
How does GraphQL change microservices API testing?
GraphQL changes microservices API testing by moving much of the compatibility risk into schema evolution, resolver behavior, query complexity, and authorization at field level. A single endpoint can hide many independent service paths.
GraphQL tests should validate persisted queries, deprecated field usage, nullability rules, resolver timeouts, batching behavior, and N plus one query risks. A schema that is technically valid can still create production incidents when an expensive query fans out across six services under peak traffic.
For federated GraphQL, add composition checks before deployment and run representative consumer queries against the composed schema. Treat resolver telemetry as part of test evidence because latency regressions may be visible only after the query planner chooses a different service path.
Contract Testing Microservices Without Blocking Independent Releases
Contract testing microservices is the practice of verifying that a service provider and its consumers agree on request and response expectations before they are deployed together. It protects independent release velocity by detecting incompatible API changes without requiring every consumer and provider to run in the same environment.
A contract is an executable agreement about an interaction, including request shape, required headers, response fields, error formats, message topics, and sometimes matching rules for dynamic values. Consumer-driven contract testing is a contract testing model where consumers publish the expectations they rely on and providers verify those expectations during their pipeline.
Pact, Spring Cloud Contract, OpenAPI validators, and schema registries all support versions of this idea. The right tool depends on whether your main risk is HTTP interaction compatibility, event schema compatibility, generated API compliance, or governance across many teams.
When should you use consumer-driven contract testing?
You should use consumer-driven contract testing when many consumers depend on a provider and provider teams need confidence that changes will not break real usage. It is especially valuable when consumers deploy independently or cannot all join a shared end-to-end test environment.
Consumer-driven contracts work best when each contract captures only what the consumer actually needs. If teams copy full provider schemas into every contract, the system becomes brittle and blocks safe additive changes.
Provider verification should run on every provider change, and consumer contract publication should run when consumer expectations change. A broker or registry then answers the release question: can this version of provider safely deploy with the currently supported consumers?
What does a provider verification pipeline look like?
A provider verification pipeline pulls the latest relevant contracts, starts the provider in a controlled test mode, executes contract interactions, and publishes verification results. It should fail fast on breaking changes and attach logs, traces, and request payloads for diagnosis.
{
  "pipeline": "orders-provider-contract-verification",
  "providerVersion": "2.18.4",
  "contractBroker": "https://contracts.example.internal",
  "consumers": ["checkout-web", "mobile-cart", "support-portal"],
  "providerBaseUrl": "http://localhost:8080",
  "publishVerificationResult": true,
  "failOn": ["missingRequiredField", "changedStatusCode", "incompatibleType"]
}
This style of pipeline is deliberately smaller than a full environment test. It isolates compatibility risk, runs in minutes, and gives both the provider and consumers a versioned audit trail.
For asynchronous systems, contracts should cover message payloads, topic names, headers, keys, partitioning assumptions, and backward-compatible schema evolution. Event compatibility failures are often more expensive than REST failures because bad messages can remain in queues or logs after deployment.
Distributed System Testing for Failure Modes and Data Consistency
Distributed system testing should prove that the system behaves acceptably when services are slow, unavailable, duplicated, reordered, or eventually consistent. Happy-path service tests cannot expose the operational failure modes that define microservices reliability.
Eventual consistency is a data model where updates become visible across services after a delay rather than in a single atomic transaction. Tests for eventual consistency must validate business tolerances, not assume immediate reads after writes.
In microservices, correctness often means compensating safely rather than never failing. A payment service may succeed while fulfillment fails, so the test must verify retry, cancellation, refund, audit events, and user-visible state.
How do you test eventual consistency without flaky sleeps?
You test eventual consistency without flaky sleeps by polling for a bounded business condition with clear timeout diagnostics. Fixed waits hide performance regressions when they are too long and create random failures when they are too short.
Use assertions such as order status becomes reserved within 20 seconds, inventory reservation event is consumed exactly once, or customer notification is emitted after payment capture. Record the actual convergence time so trends are visible in CI and staging.
Teams that replace fixed sleeps with condition-based polling often cut flaky distributed tests by 25% to 40%. The gain comes from aligning the assertion with the domain outcome instead of the test author's guess about timing.
What failures should chaos and resilience tests inject?
Chaos and resilience tests should inject the failures your architecture claims to tolerate, including latency, partial outages, duplicate messages, clock drift, throttling, and malformed downstream responses. They should begin in controlled pre-production environments before becoming production experiments.
Prioritize failure modes around revenue, identity, data integrity, and customer trust. A synthetic outage of a recommendation service is useful, but it is not as urgent as validating that checkout degrades safely when inventory becomes slow.
Measure the recovery path as carefully as the failure. A service that times out correctly but leaves orphaned reservations, stuck sagas, or unprocessed dead-letter messages has still failed the distributed system test.
Distributed Debugging Requires Observability as a Test Artifact
Distributed debugging is the process of diagnosing failures across service boundaries using correlated logs, metrics, traces, payloads, and deployment metadata. In microservices, a test failure without traceability is not a defect report; it is a search problem.
Observability is the ability to understand system behavior from emitted telemetry such as logs, metrics, traces, and events. Test automation should assert that essential telemetry exists because missing observability turns recoverable defects into long incident investigations.
OpenTelemetry is an open standard for collecting traces, metrics, and logs across distributed systems. When test harnesses propagate trace IDs, a failed API assertion can link directly to the provider span, database call, queue publish, and downstream retry.
How should trace IDs flow through test automation?
Trace IDs should be generated or captured by the test harness and passed through every API request, message, and downstream call that participates in the scenario. The same ID should appear in test reports, service logs, distributed traces, and failure screenshots when user interfaces are involved.
For API tests, send a correlation header such as traceparent or x-correlation-id and assert that the response preserves or returns it. For asynchronous workflows, include the ID in message headers so queue consumers can continue the trace.
This small discipline changes debugging time dramatically. In teams with consistent trace propagation, failed distributed test triage often drops from hours to minutes because engineers can inspect one trace instead of querying logs across many services.
What telemetry should a failing test capture?
A failing test should capture the request, sanitized response, correlation ID, service version, environment, contract version, relevant logs, trace link, and timing breakdown. It should not dump secrets, tokens, personally identifiable data, or full production-like payloads into CI artifacts.
Capture enough information to answer three questions: which component violated the expectation, whether the failure is deterministic, and what changed since the last passing run. Deployment metadata is crucial because microservices failures frequently appear after only one service rolls forward.
Telemetry assertions also belong in your suites. If a critical service returns an error without a structured error code or emits no span around a downstream call, the test should flag an operability defect before an incident exposes it.
Tooling and Technique Comparison for Microservices Testing Strategy
The best microservices testing strategy uses several complementary techniques rather than one universal tool. Each technique should have a defined feedback speed, defect class, and release gate purpose.
| Technique or tool | Best fit | Typical feedback time | Main risk covered | Common misuse |
|---|---|---|---|---|
| Service-level REST or GraphQL API tests | Validate provider behavior at the boundary | Seconds to minutes | Incorrect business response, auth failure, schema error | Checking only status codes |
| Pact consumer-driven contracts | Protect compatibility between consumers and providers | Minutes | Breaking response or request changes | Capturing full provider schemas instead of consumer needs |
| OpenAPI or GraphQL schema validation | Govern documented interface compliance | Seconds | Spec drift and schema incompatibility | Treating the spec as proof of business correctness |
| Service virtualization | Simulate unavailable or costly dependencies | Seconds to minutes | Edge cases, dependency instability, third-party limits | Using stale mocks that no longer match production |
| Workflow integration tests | Validate critical multi-service journeys | Minutes to tens of minutes | Cross-service orchestration and data propagation | Covering every permutation end to end |
| OpenTelemetry tracing | Debug distributed failures and latency paths | Runtime evidence | Unknown failure ownership and slow triage | Collecting traces without linking them to test reports |
The table is intentionally biased toward feedback economics. A test that finds a real defect after 45 minutes may still be useful, but it should not be the first signal for a change that a contract check could reject in two minutes.
Common Pitfalls That Break API Testing Microservices
Microservices testing breaks down when teams confuse environment realism with risk coverage. The result is a large, expensive suite that still misses compatibility defects, asynchronous failures, and diagnostic gaps.
The most common smell is a test portfolio shaped by organizational anxiety rather than architecture. Teams add another end-to-end test after every incident, but they do not ask whether a contract, schema, unit-level invariant, or telemetry assertion would catch the defect earlier.
Why do teams overbuild end-to-end suites?
Teams overbuild end-to-end suites because they feel closer to user reality and appear easier to explain to stakeholders. In practice, broad end-to-end suites become slow, flaky, and hard to debug once dozens of services change independently.
A healthier pattern is to keep end-to-end tests for a small set of business-critical journeys: account creation, checkout, payment reversal, entitlement changes, and compliance-sensitive reporting. Cover permutations at the API, contract, and service levels where data setup and failure diagnosis are cheaper.
If an end-to-end test fails often but rarely reveals a product defect, downgrade or redesign it. Flakiness is not just annoyance; it trains teams to ignore quality signals.
Can mocks hide production defects?
Mocks can hide production defects when they are not generated from contracts, refreshed from real provider behavior, or validated against schemas. A mock that always returns the ideal response removes the very uncertainty that microservices testing must expose.
Service virtualization should include latency, errors, pagination, missing optional fields, throttling, and versioned payloads. It should also be reviewed when provider contracts change so consumers do not pass tests against an interface that no longer exists.
The goal is not to eliminate mocks. The goal is to make mocks accountable to contracts and to reserve real dependency tests for risks that only real infrastructure can reveal.
Practical Implementation Roadmap for QA Leads
A practical rollout should start with the highest-change APIs and highest-cost incidents, then expand through standards and automation. Trying to redesign the entire enterprise test strategy at once usually creates governance documents instead of better feedback.
Begin by inventorying services, consumers, API types, deployment cadence, known incidents, and existing test duration. This identifies which services need contract testing first and which end-to-end tests are absorbing problems that should be caught lower in the stack.
How do you prioritize the first contracts?
You prioritize the first contracts by selecting interactions where provider changes frequently break consumers or where consumers cannot coordinate releases. Payment, identity, pricing, order state, entitlement, and notification APIs are common starting points.
Do not start with the easiest endpoint if it has little business value. Start where compatibility failure is expensive, then use that success to define patterns for naming, broker usage, verification gates, and ownership.
Set an adoption metric that matters, such as percentage of critical consumer interactions covered by verified contracts or reduction in compatibility defects reaching staging. Counting raw test numbers encourages low-value automation.
How should release gates use test results?
Release gates should block only on tests that are deterministic, owned, and tied to release risk. Blocking on unstable shared-environment checks creates release friction without improving quality.
Use contract verification, schema compatibility, critical API behavior tests, security boundary tests, and smoke-level workflow tests as deployment gates. Run broader resilience, performance, and exploratory distributed tests on scheduled or pre-release cadences unless the service is in a regulated or extremely high-risk domain.
Review gate effectiveness monthly. If a gate rarely fails or often fails for environmental reasons, it should be sharpened, moved, or removed.
Key Takeaways
- A microservices testing strategy should optimize for fast, owned, risk-specific feedback rather than maximum environment realism.
- API testing microservices must validate behavior, authorization, schema semantics, error contracts, and idempotency, not just HTTP status codes.
- Contract testing microservices protects independent deployments by proving provider and consumer compatibility before services meet in an environment.
- Distributed system testing should cover latency, retries, duplicate messages, eventual consistency, and recovery paths because these are where microservices fail in production.
- Distributed debugging depends on trace IDs, structured logs, contract versions, deployment metadata, and test reports that connect directly to telemetry.
- End-to-end tests should be few, business-critical, and diagnostic; use API, contract, and service-level tests for permutations.
- Mocks and service virtualization are valuable only when they stay accountable to contracts, schemas, and realistic failure behavior.